Introducing Decision 1.0: Open Decision Foundation Models
From the next move to a whole queue of decisions. Meet Decision 1.0. Sound on.
Jev's launch has put decision models in the spotlight. The question is simple: how do we give AI systems a faster way to decide what happens next?
For vLLM Semantic Router, that means choosing the right model, applying the right policy, and moving each request forward.
Meet Decision 1.0: Open Decision Foundation Models. Six open models that turn context into decisions—built for the next action, from a single request to a whole queue of work.
Explore the six models → · Try Decision Studio →
Why the decision layer matters
A useful decision layer has to keep up with the application. Available models change. Policies evolve. A fast answer may be the right outcome for one request, while another deserves more computation. The application needs a way to express those differences and evaluate the available choices.
Decision turns that work into a small interface:
State + questions + criteria → answers.
The state carries the evidence. Questions specify what matters. Criteria describe the candidate models, actions, labels, or rubric levels. Change the criteria and the model has a new decision to make, without replacing a fixed classification head or parsing a generated explanation.
For routing, the application can supply task requirements, model capabilities, and measured operating signals as evidence. For agents, it can provide the current state and available actions. For evaluation, it can supply a completed trace and the standards it should meet. The format stays the same while the decisions change.
Built to decide
Decision scores the candidates you provide directly. Each candidate is evaluated in the context of the evidence and the question, so an option can be a short label or a description of what an action means.
Two architectural branches make this possible. Kai and Lex use three bidirectional encoder paths built on Vela, with separate interaction layers and readouts for Choice, Noul, and Score. Eos, Sol, Nox, and Lux adapt Qwen3.5 text backbones, combining Gated DeltaNet with full attention and a shared candidate head.
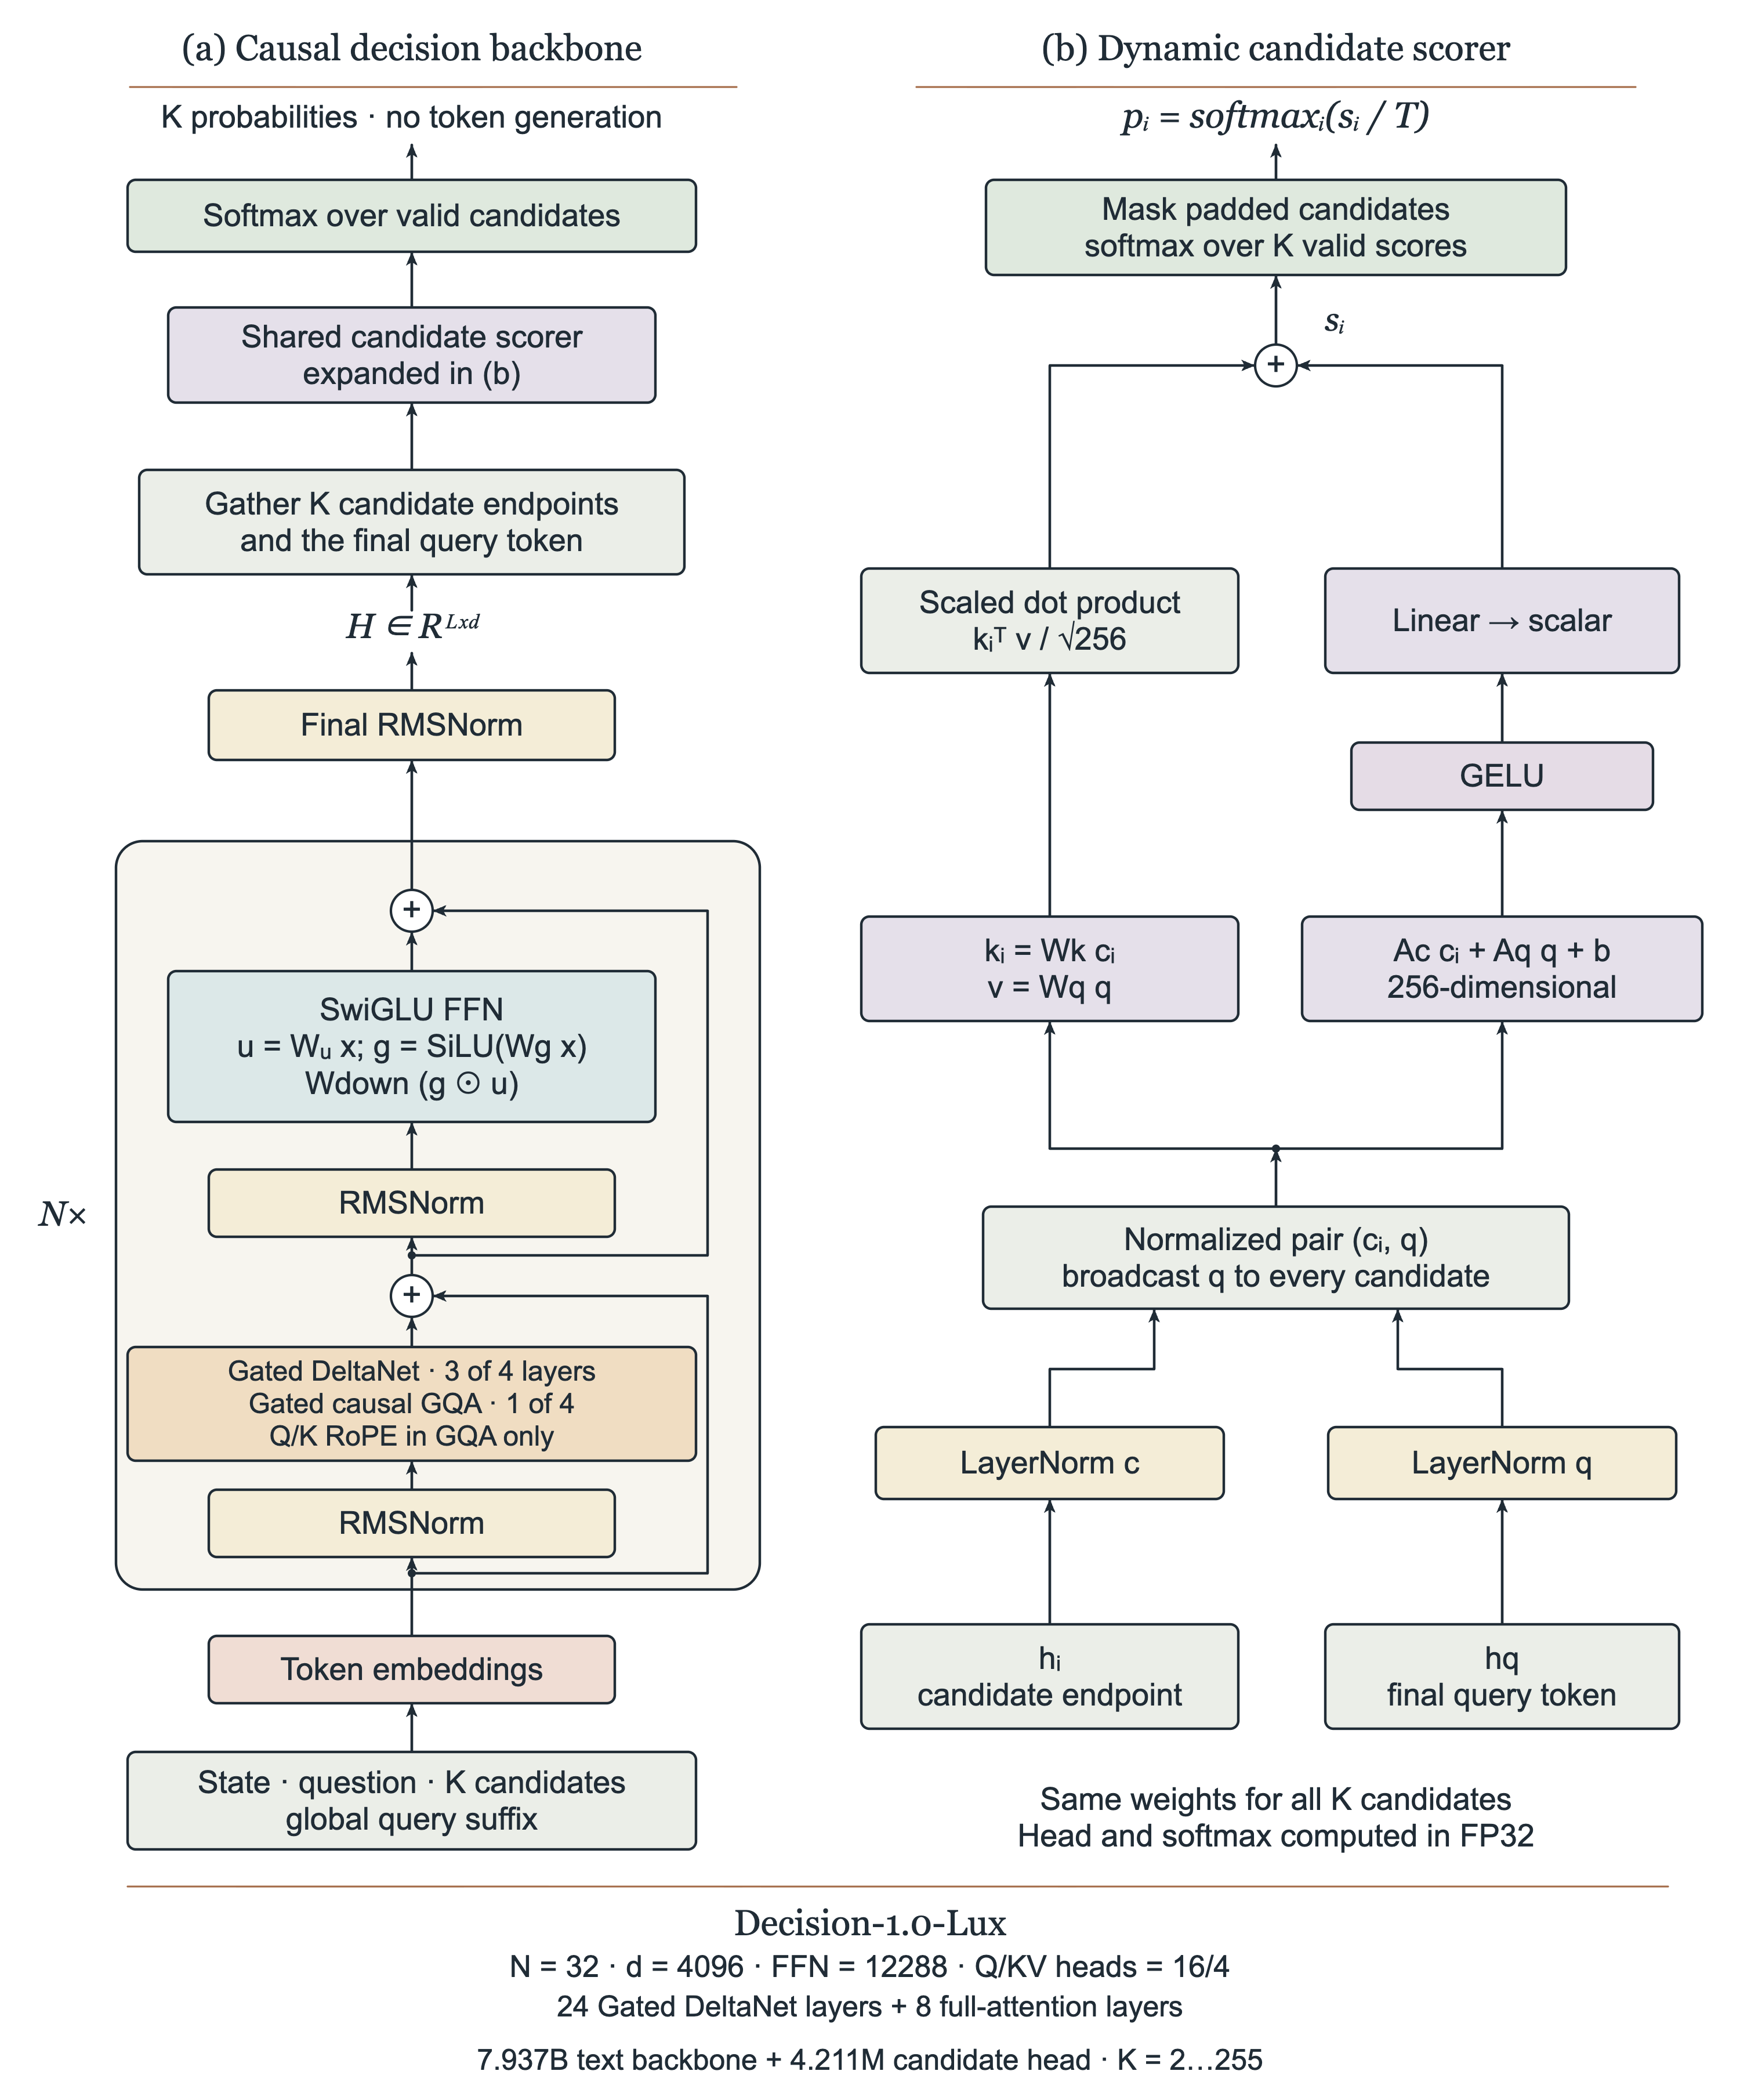
Inside Lux-9B. All candidates for one question are scored in a single forward pass. Independent questions are processed in batches.
The result is a model designed around the decision itself: compare the alternatives, return their probabilities, and let the application take the next step.
Explore the encoder branch and candidate readout
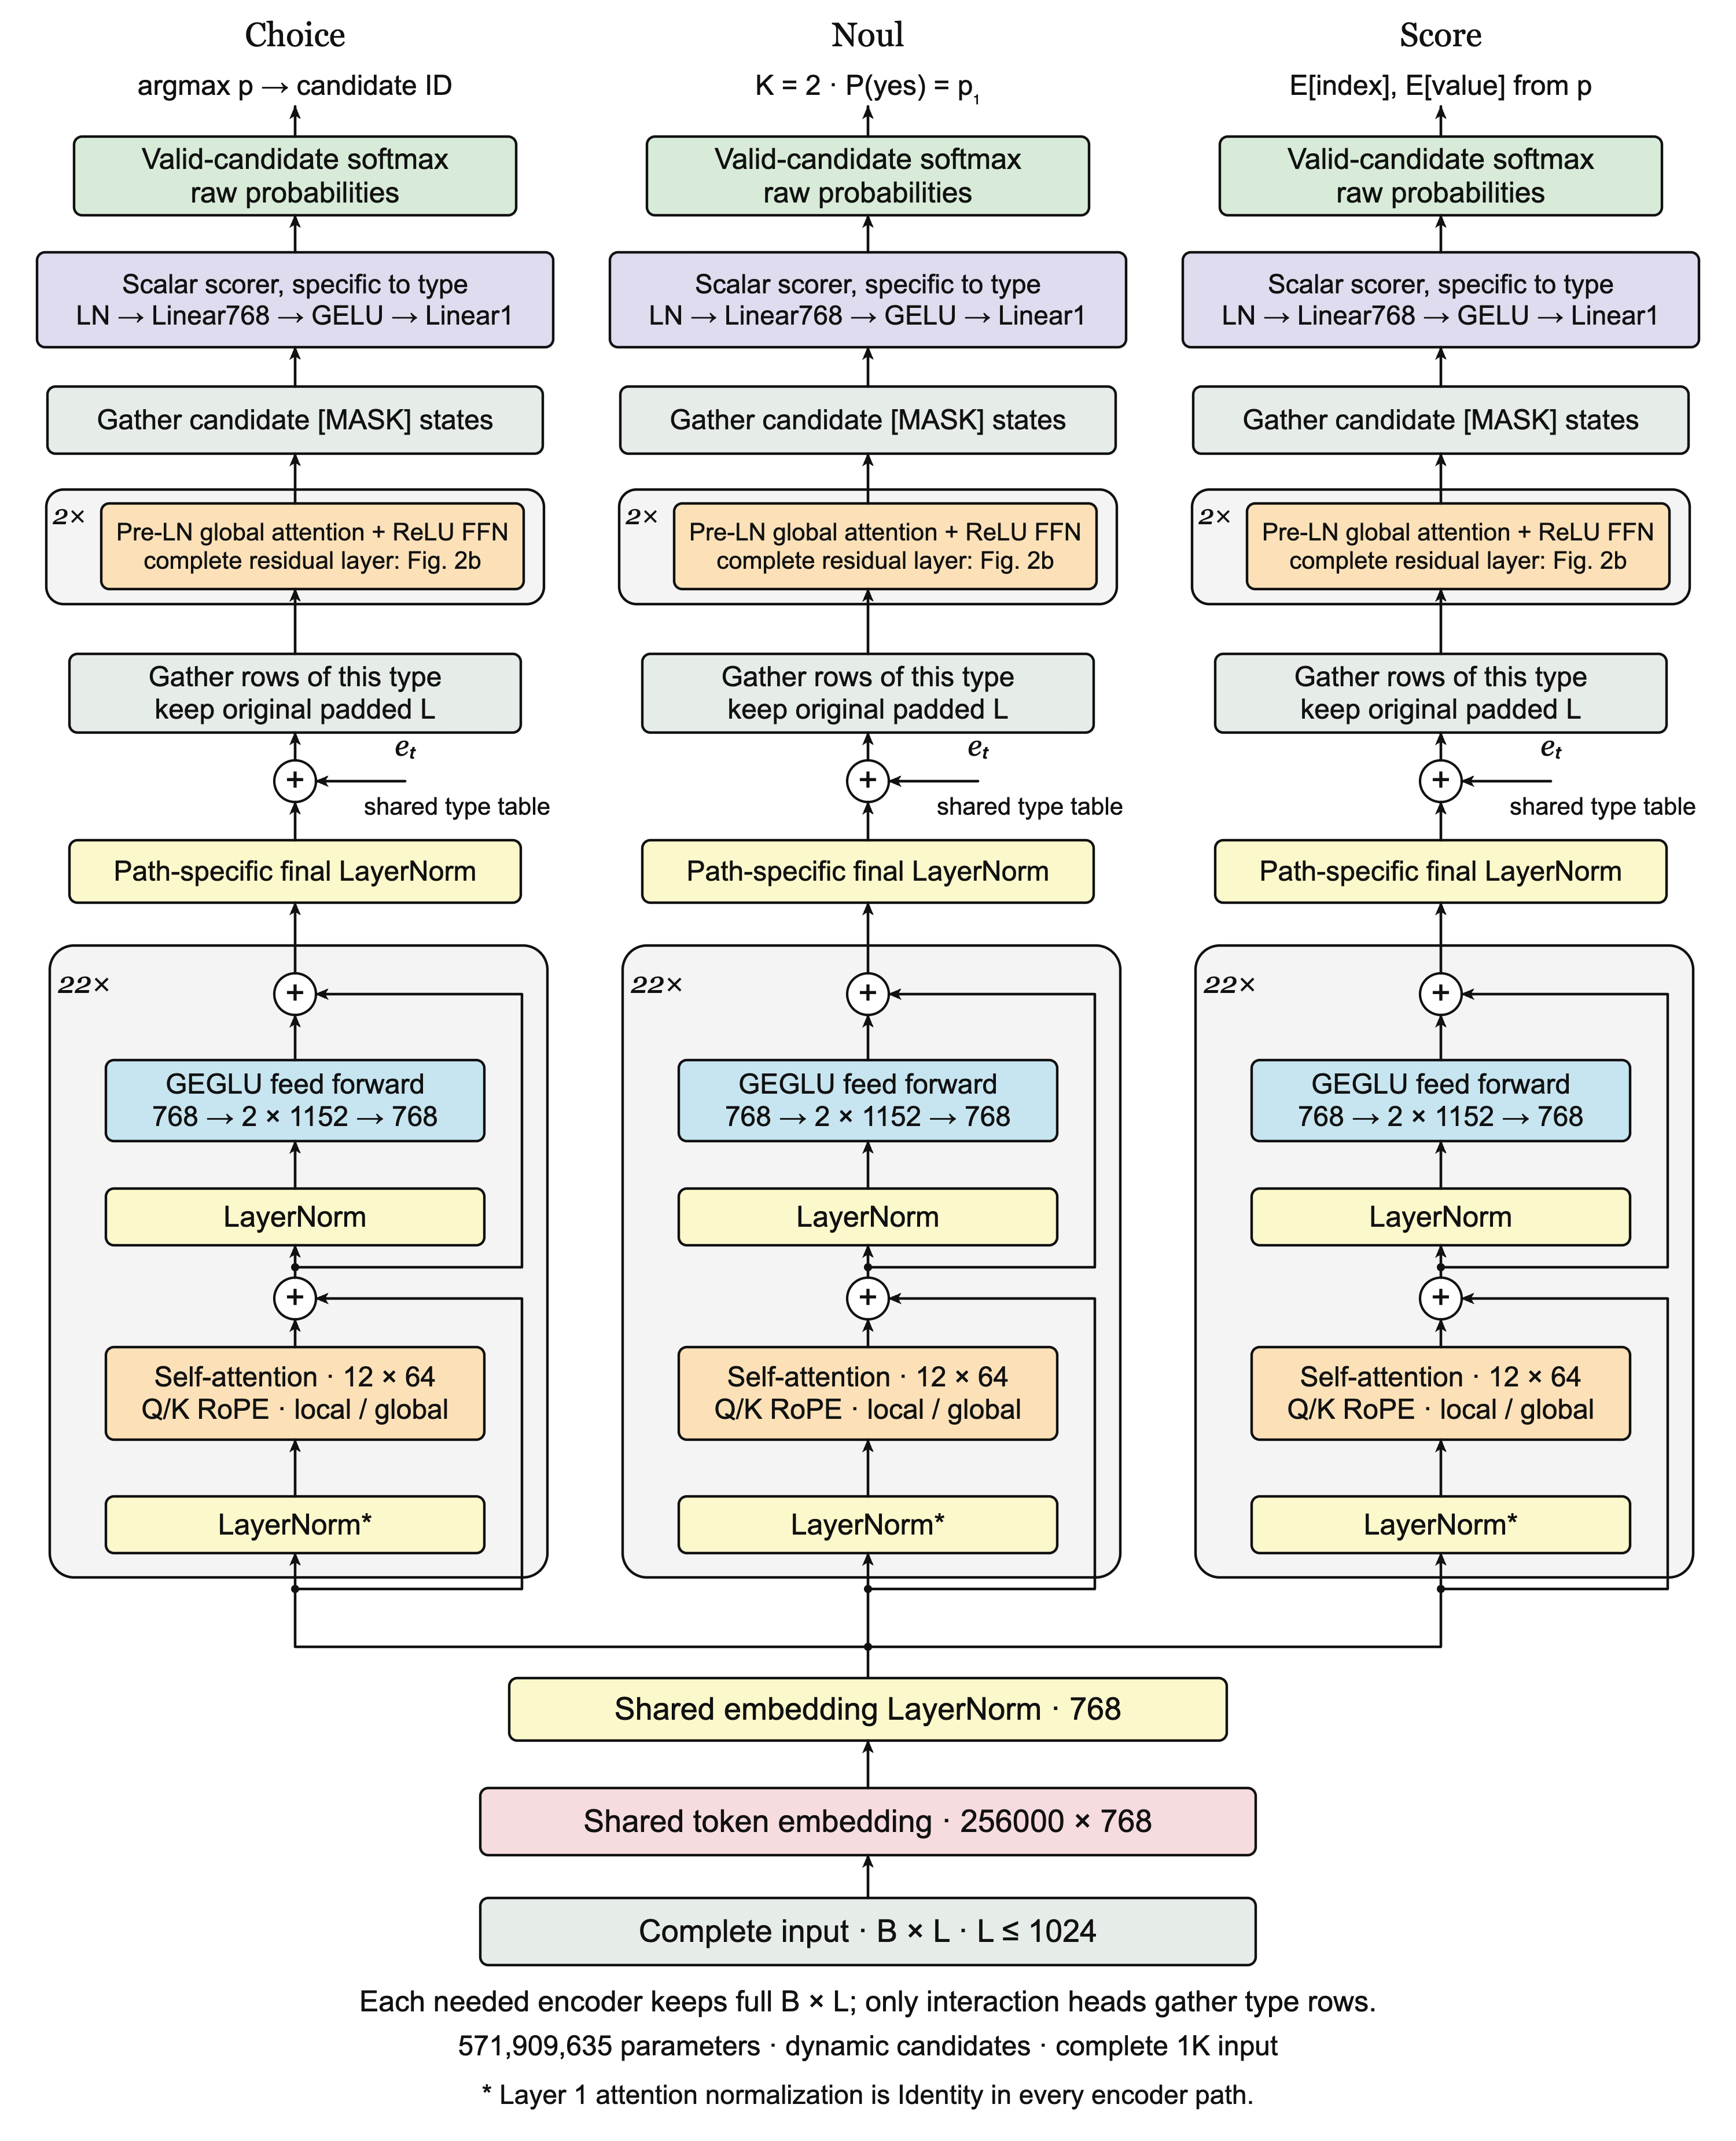
Kai's three-path encoder architecture is also used by Lex, whose weights specialize it for operational workflows.
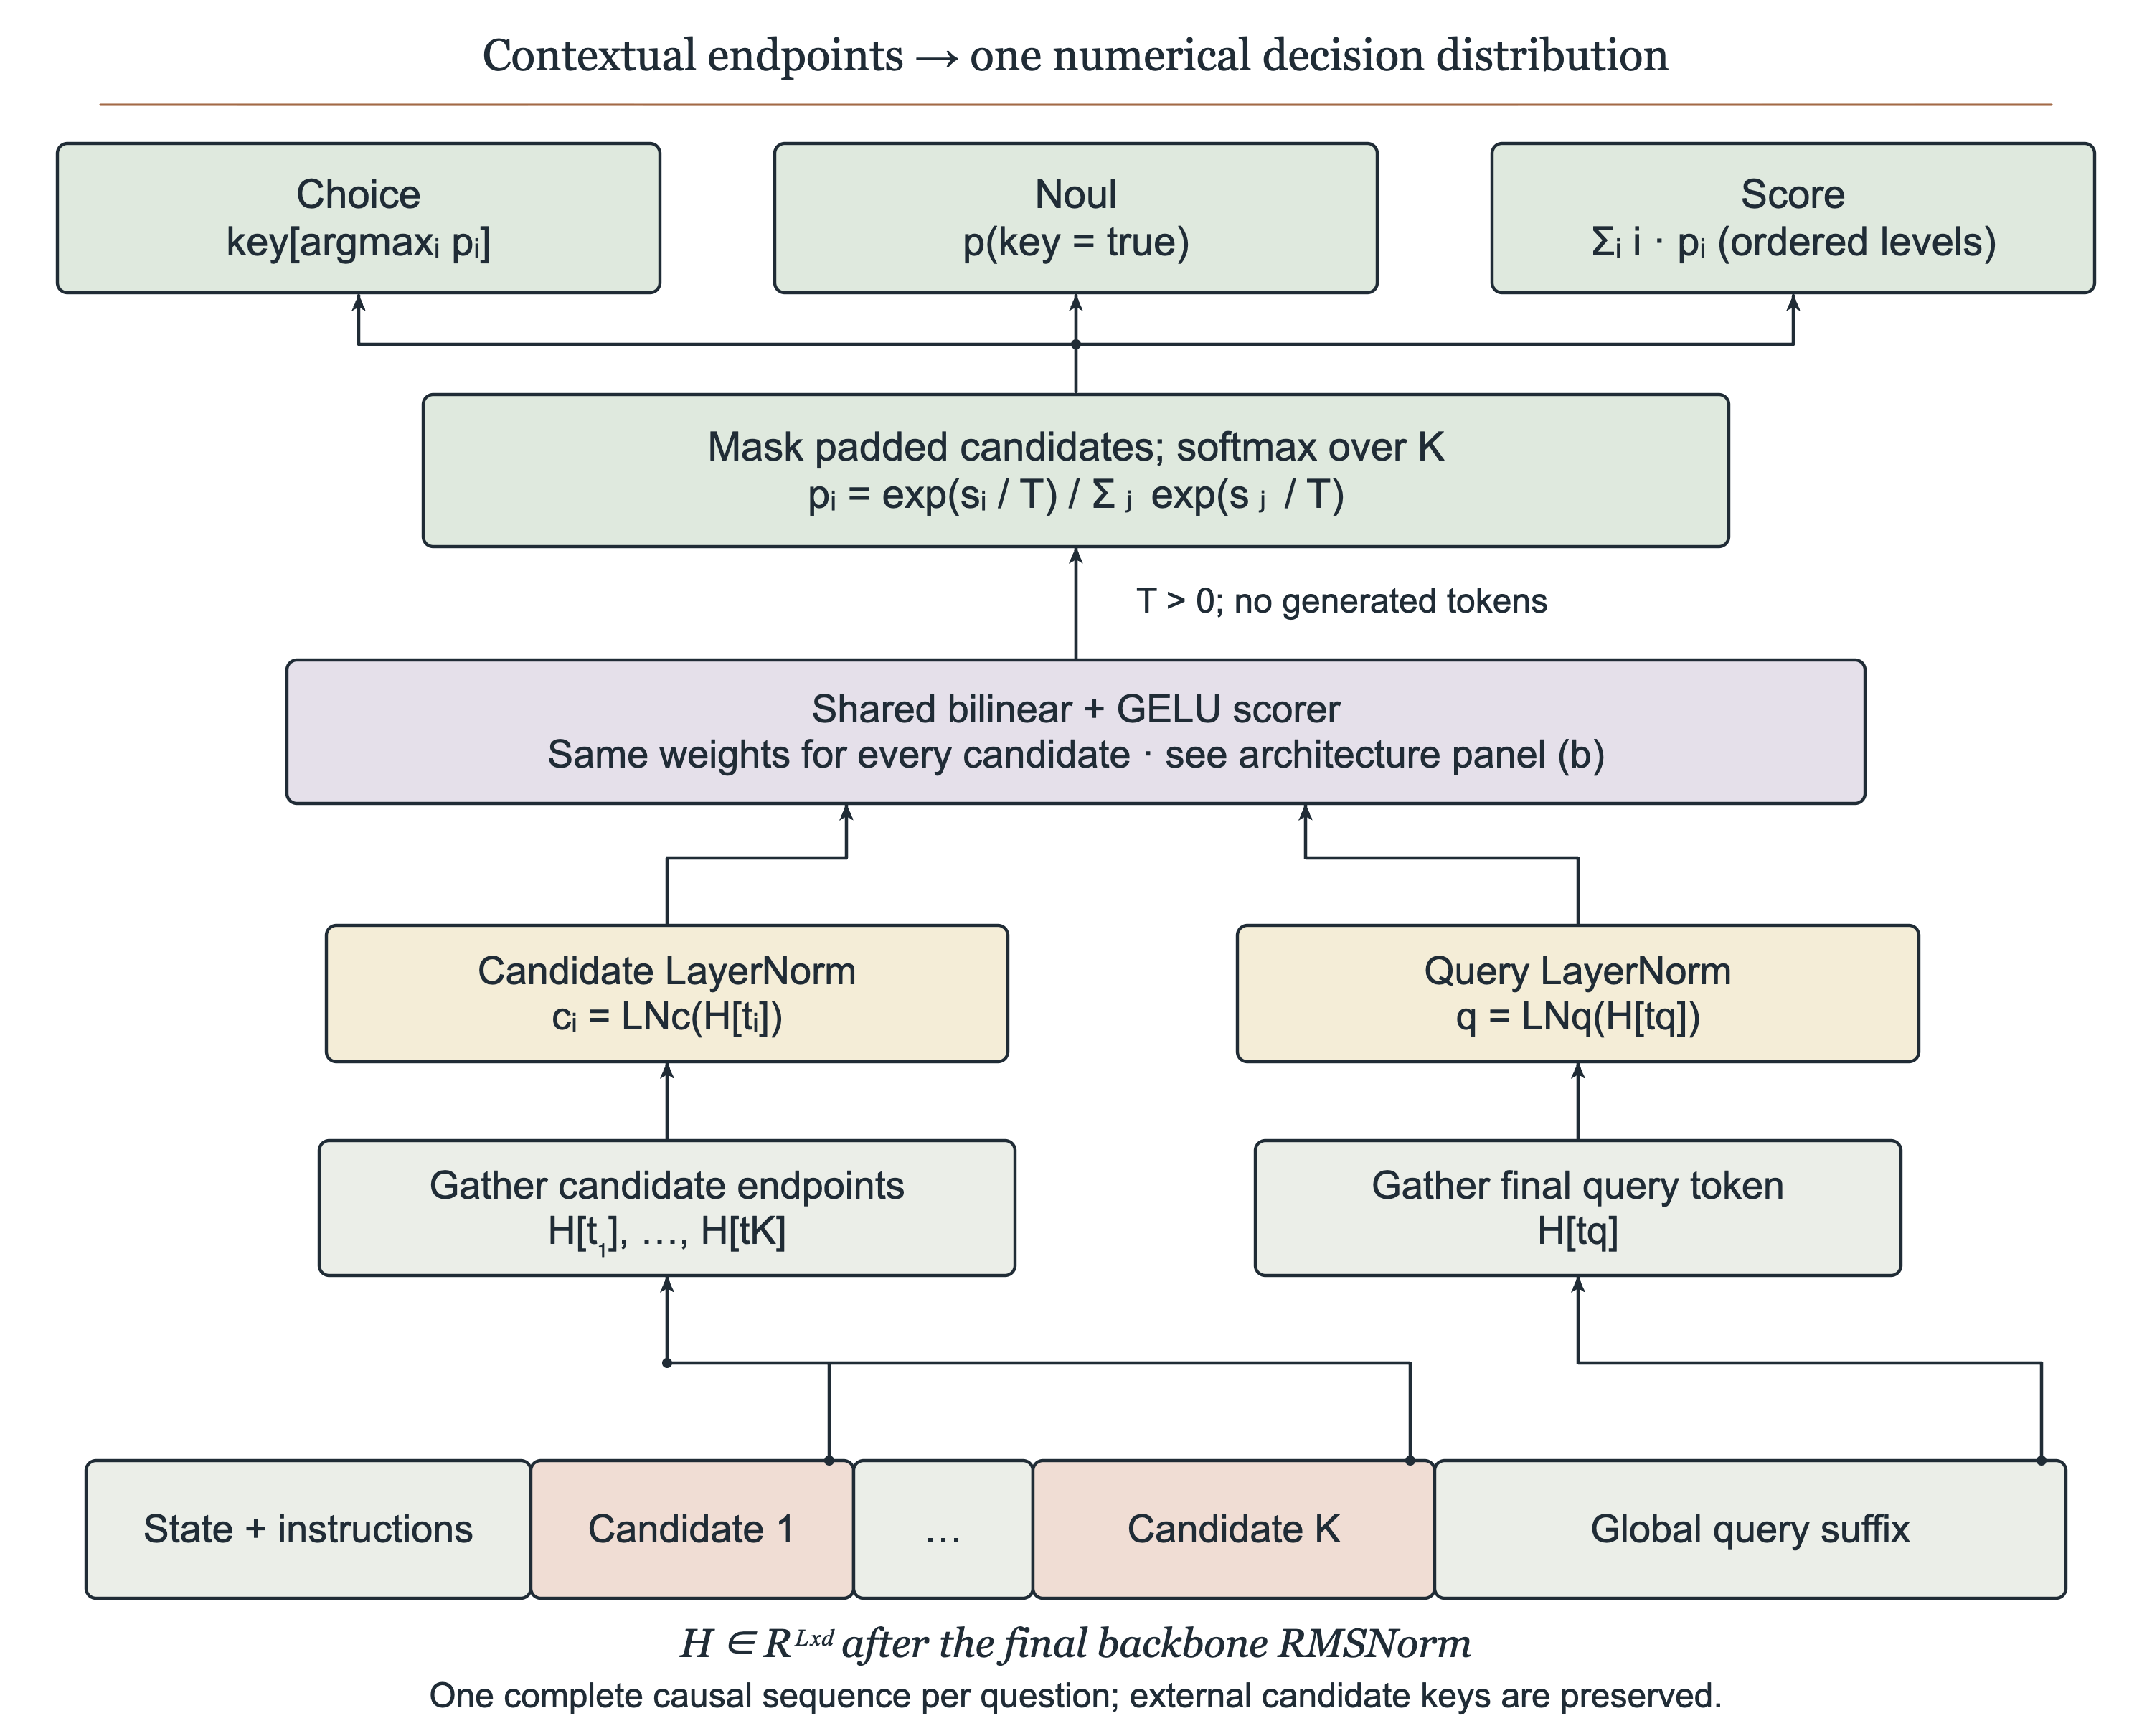
Lux's shared candidate readout. Candidate descriptions come from the request, rather than a fixed vocabulary of task labels.
Six models, one decision interface
Start with the model that fits your workload. Keep the questions, options, and rubrics as you explore the family.
| Model | Built for | Input budget |
|---|---|---|
| Decision-1.0-Kai-0.6B | A compact, general-purpose starting point for routing, conditions, and action selection. | 1,024 tokens |
| Decision-1.0-Lex-0.6B | Operational decisions: customer service, invoices, security incidents, and agent traces. | 1,024 tokens |
| Decision-1.0-Eos-0.8B | The smallest hybrid decoder, bringing longer evidence into a compact model tier. | 16,384 tokens |
| Decision-1.0-Sol-2B | The next step in capacity for decisions over extended context. | 16,384 tokens |
| Decision-1.0-Nox-4B | More capacity for combining conditions, applying rules, and choosing actions. | 16,384 tokens |
| Decision-1.0-Lux-9B | Our largest model and strongest overall result on the released decision suite. | 16,384 tokens |
Input budgets cover the complete state, question, and candidate descriptions. The model cards document each release's architecture and runtime requirements.
Three answers your software can use
Choice picks an option. Noul judges a condition. Score applies an ordered rubric. Together, they cover the decisions inside a much larger workflow.
Consider a customer who reports a damaged parcel and requests a replacement today:
| Type | Ask the model | Use the answer |
|---|---|---|
| Choice | Which team should handle this: delivery, billing, or technical support? | Route the request using the selected candidate ID and its distribution. |
| Noul | Does the customer request action today? | Use the probability of yes to decide whether to escalate. |
| Score | Rate urgency on a scale: can wait, this week, today. | Prioritize the queue using the level distribution and expected score. |
The options are yours. A Choice can select a tool, a backend, or an available game action. A Noul can check a refund condition or whether an answer is supported by evidence. A Score can apply your review rubric to documents or completed agent runs. Score levels are ordered from zero; Noul returns a probability, with the action threshold set by your application.
One context. Many questions. Whole batches.
A single support record can need a destination, a refund check, an escalation decision, and a priority score. Apply those four questions to 128 records and you have 512 decisions in one local SDK batch submission.
Kai and Lex's native Python API accepts up to 128 independent requests and 512 total decisions, preserving request and question order. The runtime groups work into physical batches; 512 describes submission capacity, not simultaneous forwards or measured throughput. Batch API.
This is where a decision model becomes useful across an entire operation: apply a policy to a stack of invoices, triage a stream of incidents, or assess thousands of agent traces in successive batches. Define the questions once, bring new contexts, and collect structured answers ready for the next stage of the workflow.
Measured across 54 tasks
The published comparison spans 3,766 scored decisions across a selected 54-task suite covering decisions, composition, reading, inference, and transfer. Lux reaches 76.94 overall, ahead of the displayed open-model references, including Kev-9B at 71.89. Nox reaches 73.09, followed by Sol at 66.32, Eos at 61.89, and Kai at 53.52.
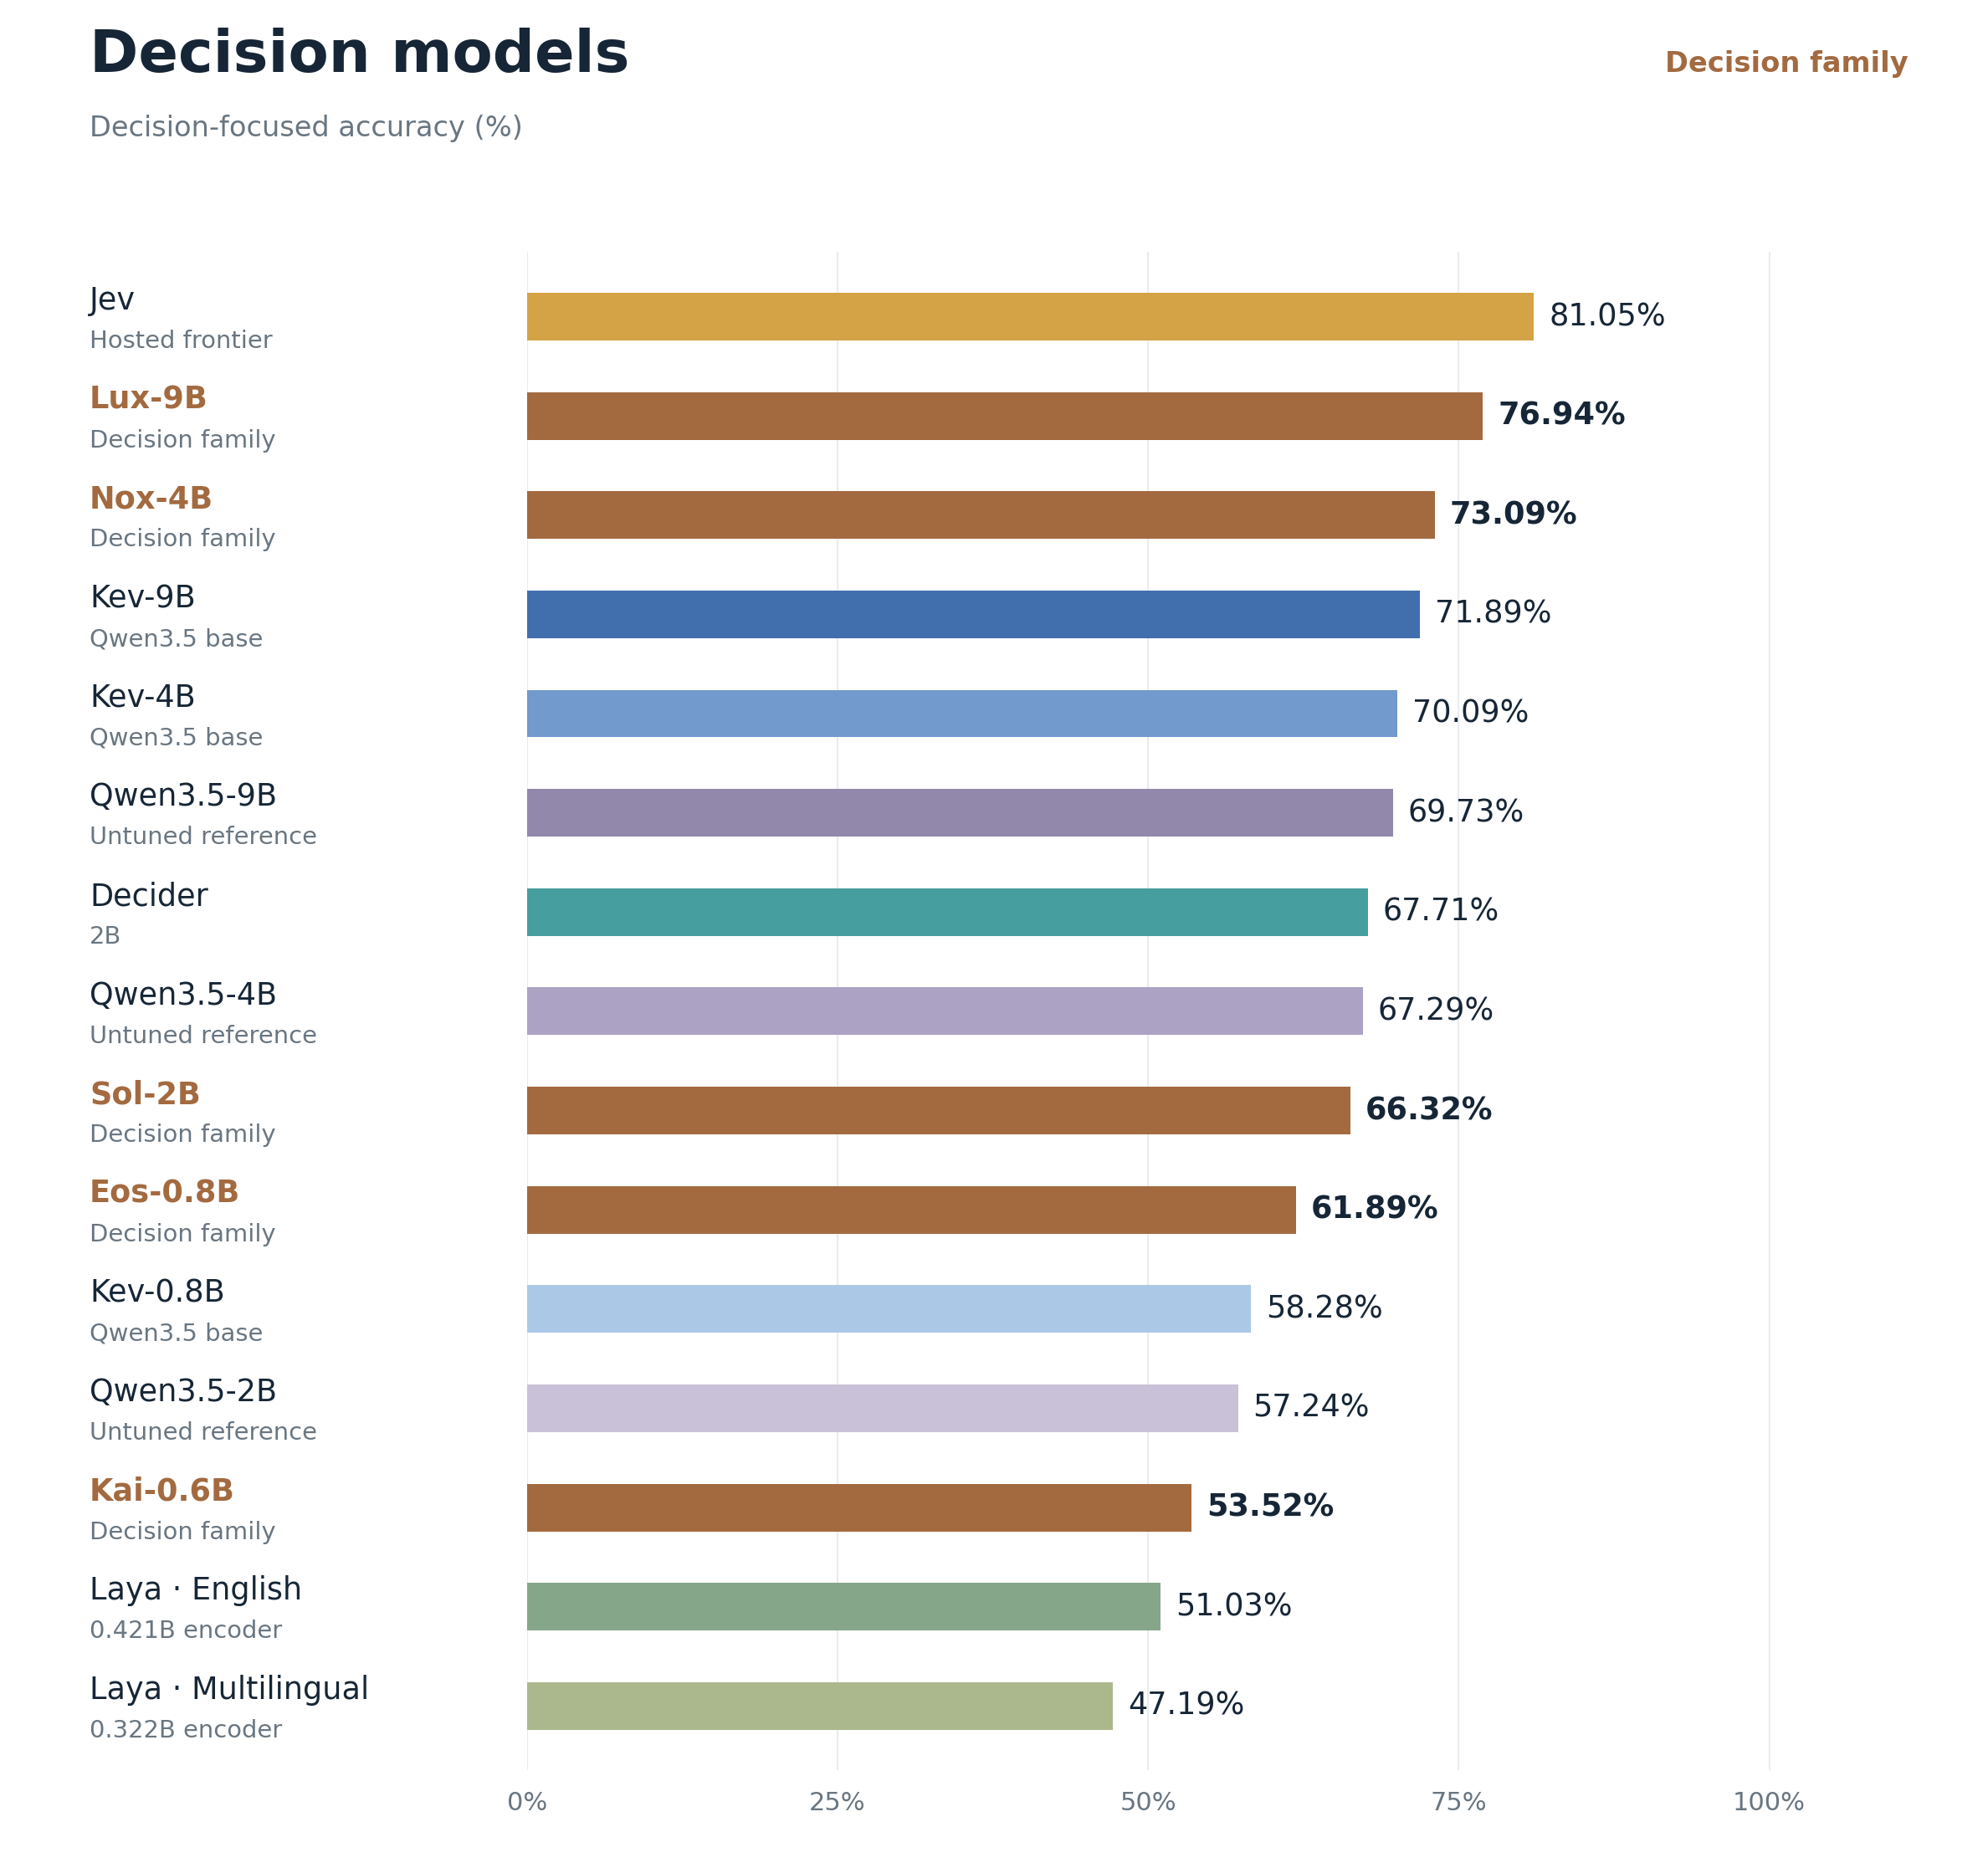
Lux leads the displayed open-model references on this suite. The hosted Jev reference remains higher overall at 81.05.
The capability matrix shows where each model stands. Lux reaches 84.10 on Decisions and 91.46 on Inference. Nox leads the displayed Decision models in Composition. Use the panels to find a starting point for the work you want to build, then evaluate on your own examples.
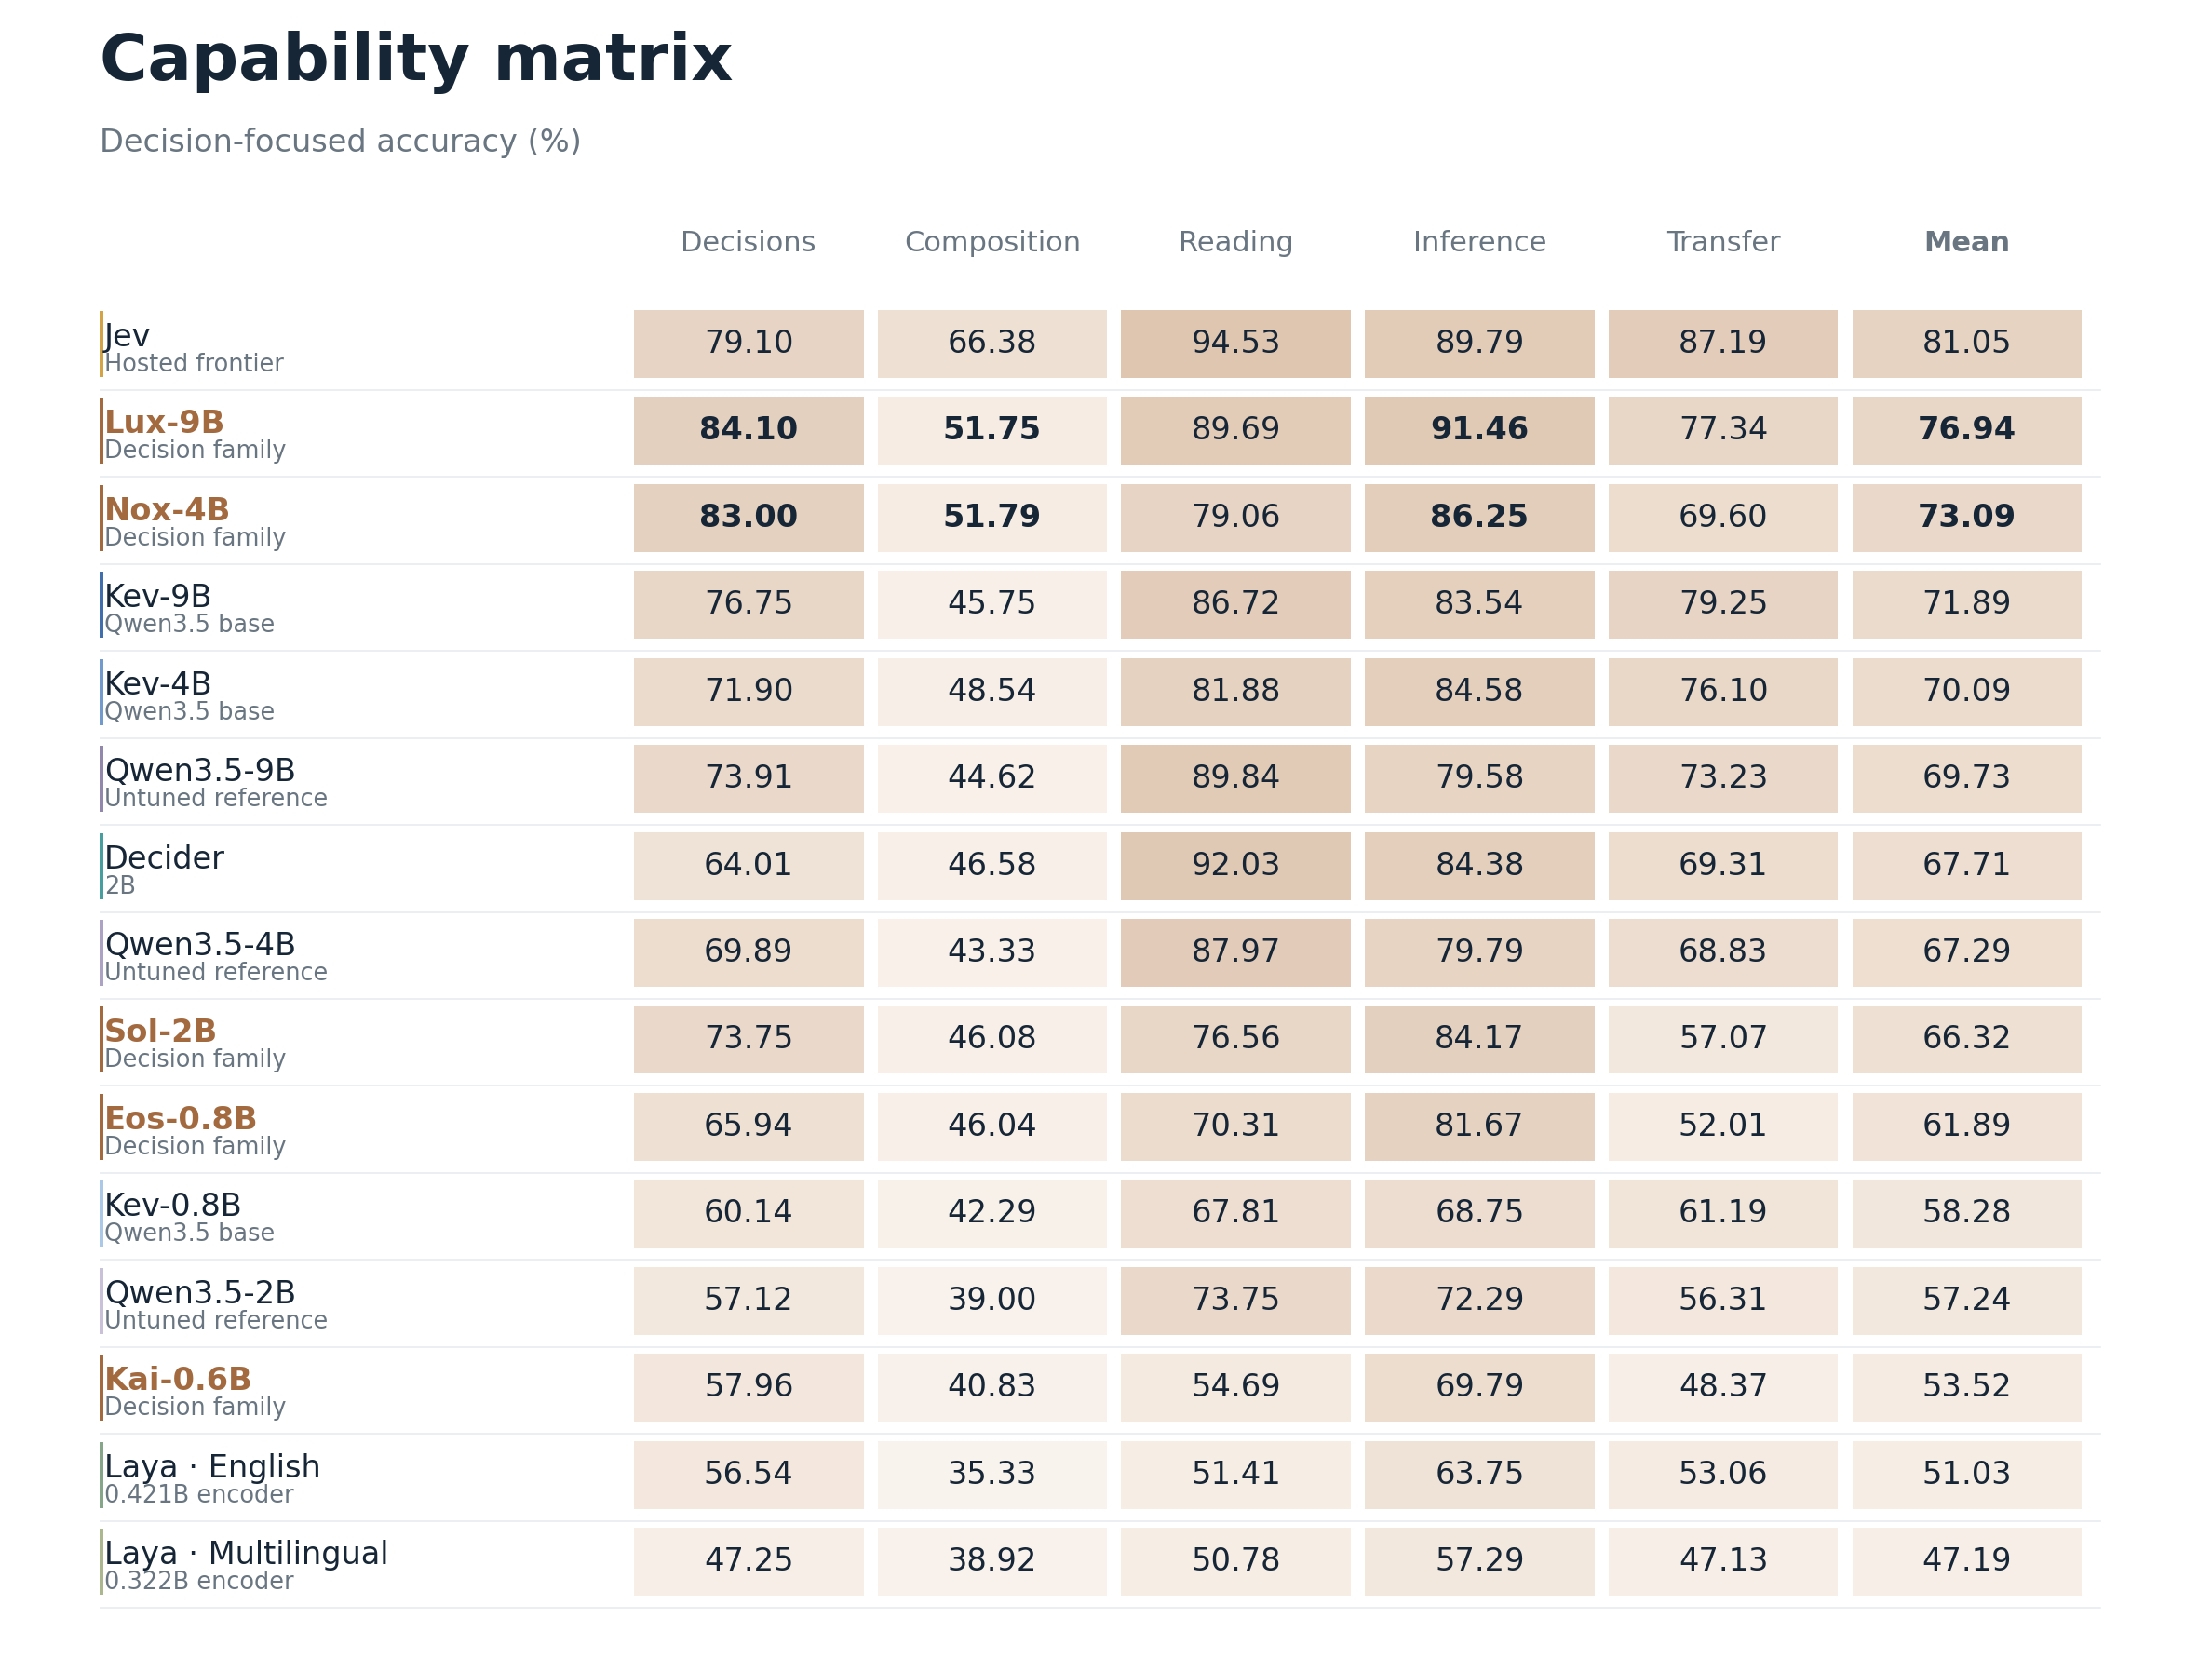
One family, different strengths. Results use the release's selected tasks and weighted overall metric.
Bring your System One workflow
Decision uses the upstream System One request format: state, model, and named questions. The latest model cards show how to use the official TypeSafe Python SDK or an equivalent HTTP request with your own SystemOne-compatible deployment.
Configure that deployment to serve Decision-1.0-Lux-9B, then replace the placeholder URL and key below. The model repositories provide weights and local inference code; an HTTP endpoint must be deployed separately.
pip install typesafe-sdk
Published request example from the Lux model card:
from typesafe_sdk import Choice, Noul, TypeSafeClient

with TypeSafeClient(
    api_key="YOUR_ENDPOINT_API_KEY",
    base_url="https://your-decision-endpoint.example",
    model="Decision-1.0-Lux-9B",
) as client:
    result = client.system_one(
        state="Customer reports a duplicate charge and asks for a refund.",
        questions={
            "route": Choice(
                instructions="Which team should handle this request?",
                criteria={
                    "billing": "Payments and refunds",
                    "technical": "Product faults",
                },
            ),
            "refund_requested": Noul(
                instructions="Did the customer request a refund?"
            ),
        },
    )
    print(result.choices["route"].choice)
    print(result.nouls["refund_requested"].noul)
The same questions with curl:
curl -X POST 'https://your-decision-endpoint.example/v1/systemone' \
  -H 'Authorization: Bearer YOUR_ENDPOINT_API_KEY' \
  -H 'Content-Type: application/json' \
  --data-raw '{
    "model": "Decision-1.0-Lux-9B",
    "state": "Customer reports a duplicate charge and asks for a refund.",
    "questions": {
      "route": {
        "type": "choice",
        "instructions": "Which team should handle this request?",
        "criteria": {
          "billing": "Payments and refunds",
          "technical": "Product faults"
        }
      },
      "refund_requested": {
        "type": "noul",
        "instructions": "Did the customer request a refund?"
      }
    }
  }'
To try Kai, configure its Decision-1.0-Kai-0.6B deployment alias and keep the same request structure. Its SDK and curl guide walks through delivery routing and urgency. Add questions to inspect another dimension of the state, or reuse the questions with new contexts.
Next: an open decision runtime
Our next step is native Decision integration in vLLM Semantic Router. We want vLLM-SR to become a runtime for decision models, with support for an Open Decision API that brings model execution and application decisions together.
For routing, that means using request context, candidate capabilities, and measured operating signals to make better model choices under quality, cost, and latency constraints. Alongside that native path, we plan to retain a System One-compatible general decision API, so the same family can serve agent actions, policy checks, and evaluation workflows beyond routing.
This is the roadmap ahead. Today's release provides the models and local inference interfaces; native vLLM-SR integration and Open Decision API support are planned next.
Build your next move
Start in Decision Studio, download a model, or bring the System One format into your application. Kai and Lex also include fine-tuning tools for adapting decisions to your own data. Decision's contributions use Apache 2.0, with retained upstream terms documented in each repository.
Open models. Your questions. Your next move.
Get Decision 1.0 → · Explore the playground → · Build with vLLM-SR →