How vLLM Semantic Router Trains Embedding Models and Publishes Them to Hugging Face

vLLM Semantic Router does not only forward prompts to one LLM. It classifies and routes requests using signals — keywords, classifiers, and embeddings.
Embeddings turn text into vectors. The router then:
- matches a query to category or anchor prompts (routing signals), or
- decides whether a new query is similar enough to reuse a semantic cache hit.
A general-purpose embedder (for example MiniLM) is good on average, but weak on specialized language (medical, law, code). So the project fine-tunes embeddings for those jobs, then publishes them on Hugging Face for everyone to download.
Training does not live inside the Go router. It lives under
src/training/model_embeddings/
(Python). Maintained models and datasets live under the official
vllm-sr organization.
For full technical details, see the maintained Router Embeddings & Hugging Face Guide.
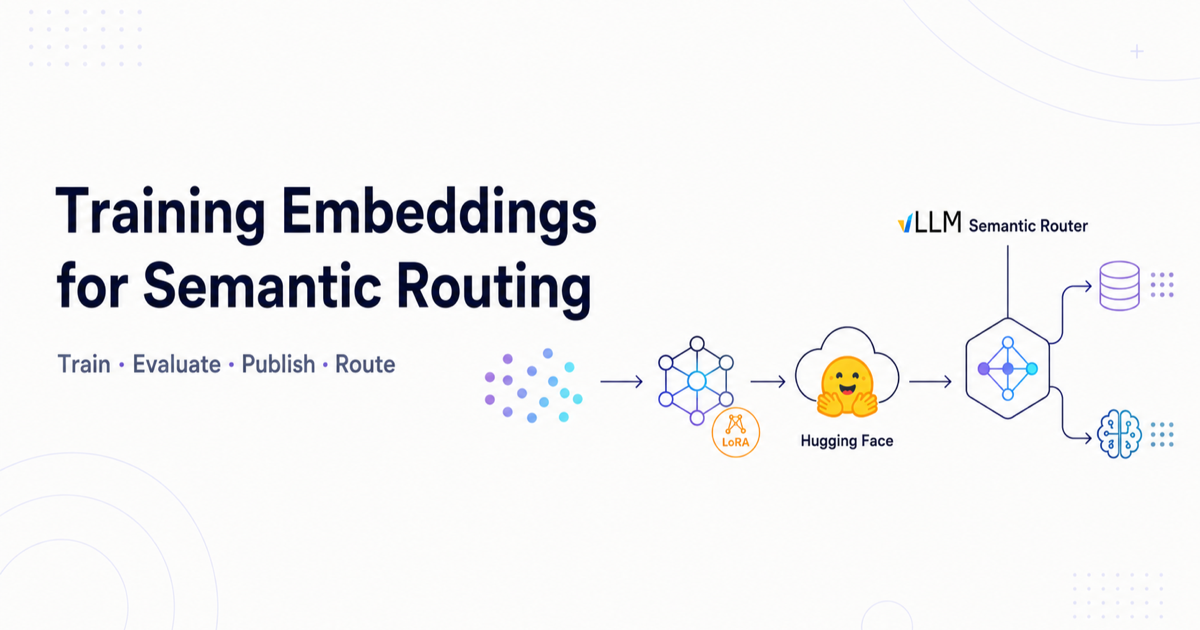
End-to-end picture
Domain data (queries / Q&A)
        ↓
Build training triplets (anchor, positive, negative)
        ↓
Fine-tune base embedding model (LoRA or full)
        ↓
Evaluate (margin / MRR / recall)
        ↓
Upload to Hugging Face (<your-hf-namespace>/... or vllm-sr/...)
        ↓
Users / CI download model
        ↓
Semantic Router uses it for routing or cache similarity
There are two main pipelines.
Pipeline A — Cache embedding LoRA
Path:
src/training/model_embeddings/cache_embeddings/
Job: Improve semantic cache accuracy so “same intent” hits and “related but different” misses.
Step 1 — Collect unlabeled queries
Prepare a JSONL file with one query per line for a domain (for example medical
questions). See
domains/README.md.
Step 2 — Generate triplets with an LLM
generate_training_data.py runs vLLM in-process on local GPUs (requiring CUDA and tensor parallelism support) to build contrastive triplets from input JSONL rows containing {"query": "..."}:
| Field | Meaning | Example |
|---|---|---|
| Anchor | Paraphrase (generated query variant) | “How do doctors diagnose diabetes?” |
| Positive | Same meaning (original seed query) | Original query |
| Negative | Distinct question / related but different intent | “What are diabetes symptoms?” |
That teaches: paraphrases should be close; near-misses should stay apart — exactly what a cache needs.
python3 src/training/model_embeddings/cache_embeddings/generate_training_data.py \
  --input data/cache_embeddings/medical/unlabeled_queries.jsonl \
  --domain medical \
  --output data/cache_embeddings/medical/triplets.jsonl \
  --max-queries 10000
Step 3 — Train a LoRA adapter
lora_trainer.py fine-tunes a small LoRA on a base such as
sentence-transformers/all-MiniLM-L12-v2.
- LoRA is small (on the order of hundreds of KB), not a full retrain.
- Training uses contrastive / MNR-style loss on triplets.
python3 src/training/model_embeddings/cache_embeddings/lora_trainer.py \
  --train-data data/cache_embeddings/medical/triplets.jsonl \
  --base-model sentence-transformers/all-MiniLM-L12-v2 \
  --output models/cache/medical-cache-lora \
  --epochs 1
You can also train a multi-domain adapter by concatenating domain triplet files and training once.
Step 4 — Evaluate
Primary cache metric:
margin = avg(similarity to positives) − avg(similarity to negatives)
Higher margin means better separation and fewer false cache hits.
python3 src/training/model_embeddings/cache_embeddings/evaluate_multi_domain.py \
  --lora-path models/cache/medical-cache-lora \
  --sample-size 2000
Step 5 — Push to Hugging Face
Authenticate using standard environment variables and upload to your Hugging Face namespace (or vllm-sr if authorized):
cd models/cache/medical-cache-lora
export HF_TOKEN="hf_your_token"
huggingface-cli login --token "$HF_TOKEN"
huggingface-cli upload <your-hf-namespace>/medical-cache-lora . --repo-type model
Step 6 — Consume
Download the adapter, attach it to the base MiniLM with PEFT, and encode queries for cache similarity:
from sentence_transformers import SentenceTransformer
from peft import PeftModel

base_model = SentenceTransformer("sentence-transformers/all-MiniLM-L12-v2")
base_model[0].auto_model = PeftModel.from_pretrained(
    base_model[0].auto_model,
    "<your-hf-namespace>/medical-cache-lora",
)
embedding = base_model.encode("What are the symptoms of diabetes?")
(Note: Cache LoRA adapters can be verified through PEFT directly in Python; native Router-side LoRA loading is a separate capability, and production Semantic Router configurations bind full embedding models.)
Pipeline B — Domain-adapted full embeddings
Path:
src/training/model_embeddings/domain_adapted_embeddings/
Job: Better retrieval / domain routing vectors (for example medical), not only cache LoRA.
Inspired by Adaptation of Embedding Models to Financial Filings via LLM Distillation.
Step 1 — Prepare data
prepare_data.py loads a Hugging Face dataset or custom Q&A JSON (question →
answering passage).
python src/training/model_embeddings/domain_adapted_embeddings/prepare_data.py \
  --source huggingface \
  --dataset keivalya/MedQuad-MedicalQnADataset
Step 2 — Iterative hard-negative mining
- Embed with the current model.
- Mine hard triplets (true docs ranked low; wrong docs ranked high).
- Keep some easy triplets so the model does not forget.
- Fine-tune with TripletLoss (margin ≈ 0.1).
- Repeat about two iterations, accumulating triplets.
Base model is often mmbert-embed-32k-2d-matryoshka.
python src/training/model_embeddings/domain_adapted_embeddings/train.py \
  --data-dir data \
  --output-dir models/trained \
  --base-model vllm-sr/mmbert-embed-32k-2d-matryoshka \
  --iterations 2 \
  --learning-rate 5e-5 \
  --margin 0.1
Critical knobs: learning rate 5e-5, margin 0.1, easy:hard ratio about 2:1,
and accumulate triplets across iterations.
Step 3 — Measure gains
On MedQuAD, MRR@5 improved by +71.18% over the baseline after two iterations (lr=5e-5, recorded in src/training/model_embeddings/domain_adapted_embeddings/train.py).
The published model is
mmbert-embed-medical.
Step 4 — Upload the full model to Hugging Face
Same pattern: local models/trained/best → huggingface-cli upload to
<your-hf-namespace>/... (or vllm-sr/... when approved for official publication).
How Hugging Face fits (publish + pull)
| Phase | What happens |
|---|---|
| Publish | Authenticate with HF_TOKEN and upload to your personal namespace (<your-hf-namespace>) or the official vllm-sr org |
| Discover | huggingface.co/vllm-sr |
| Pull | CI, docs, and users use snapshot_download / hf_hub_download / model id in config |
| Iterate | New domain data or a better recipe → retrain → new revision on the Hub |
Training is continuous in spirit: better data or hyperparameters → new fine-tune → new Hub upload.
How this reconnects to the running router
User prompt
  → Embedding model (from HF / local cache)
  → Vector similarity vs anchors / cache entries
  → Signal(s)
  → Decision (AND/OR rules)
  → Algorithm (confidence, fusion, …)
  → Backend LLM
We do not train the chat LLM for routing. We train small embedding models so the router’s similarity signals stay accurate for real domains, then ship those models on Hugging Face as shared community assets.
Try it yourself
| Track | Start here |
|---|---|
| Maintained Guide | Router Embeddings & Hugging Face Guide |
| Cache LoRA | cache_embeddings/README.md |
| Domain full fine-tune | domain_adapted_embeddings/USAGE.md |
| Hub org | vllm-sr |
One-line summary
vLLM Semantic Router fine-tunes embedding models with contrastive/triplet
learning on domain triplets, uploads them to Hugging Face (such as the vllm-sr
organization or community repositories), and downloads them at runtime so routing and semantic cache similarity
stay accurate.